Description
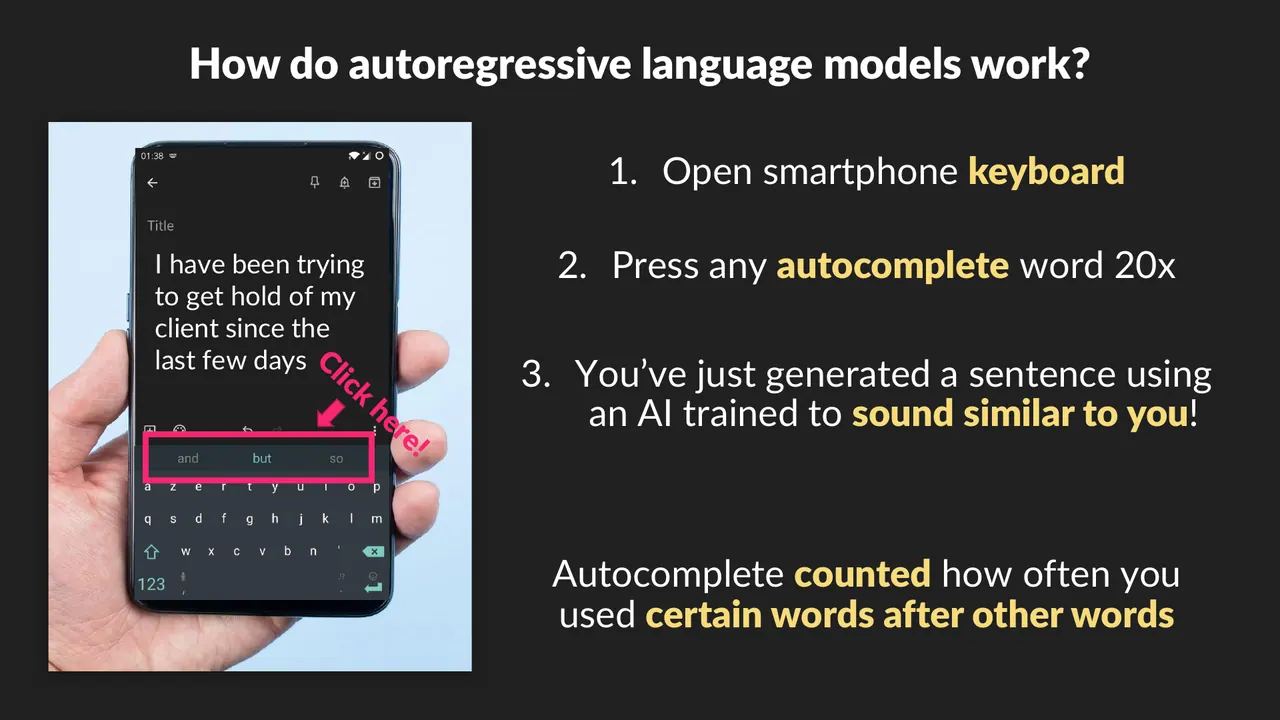
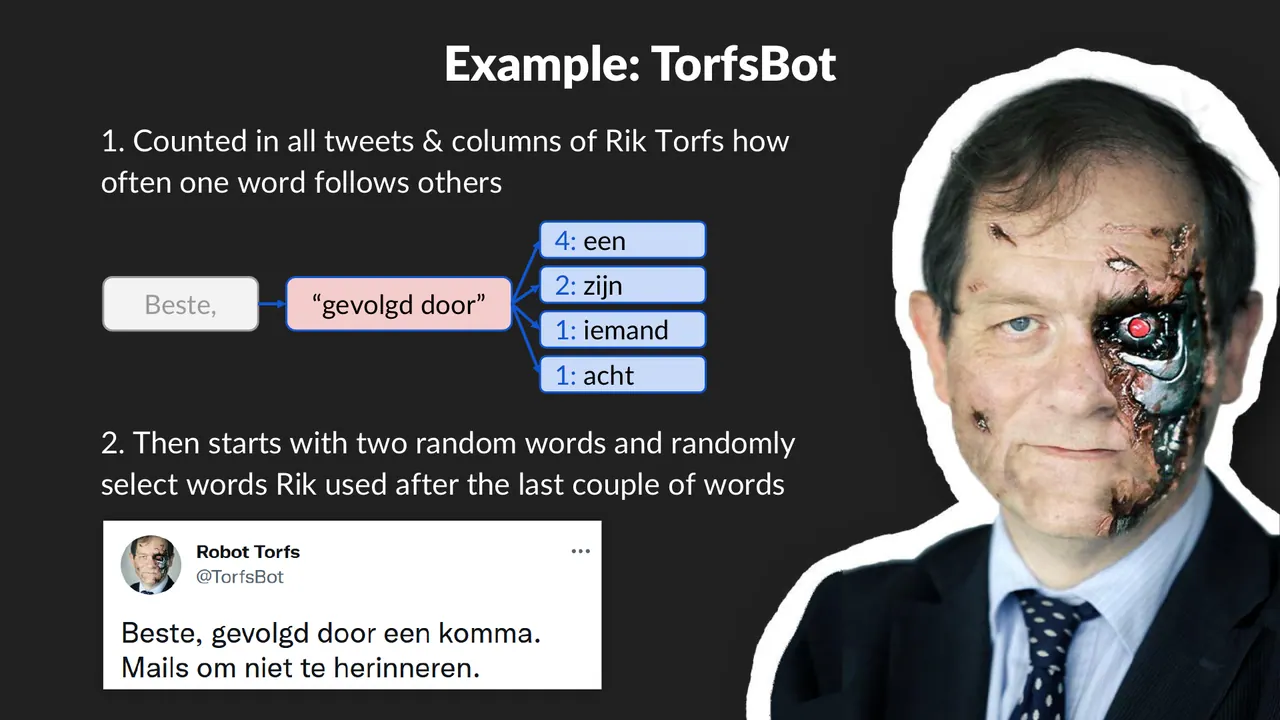
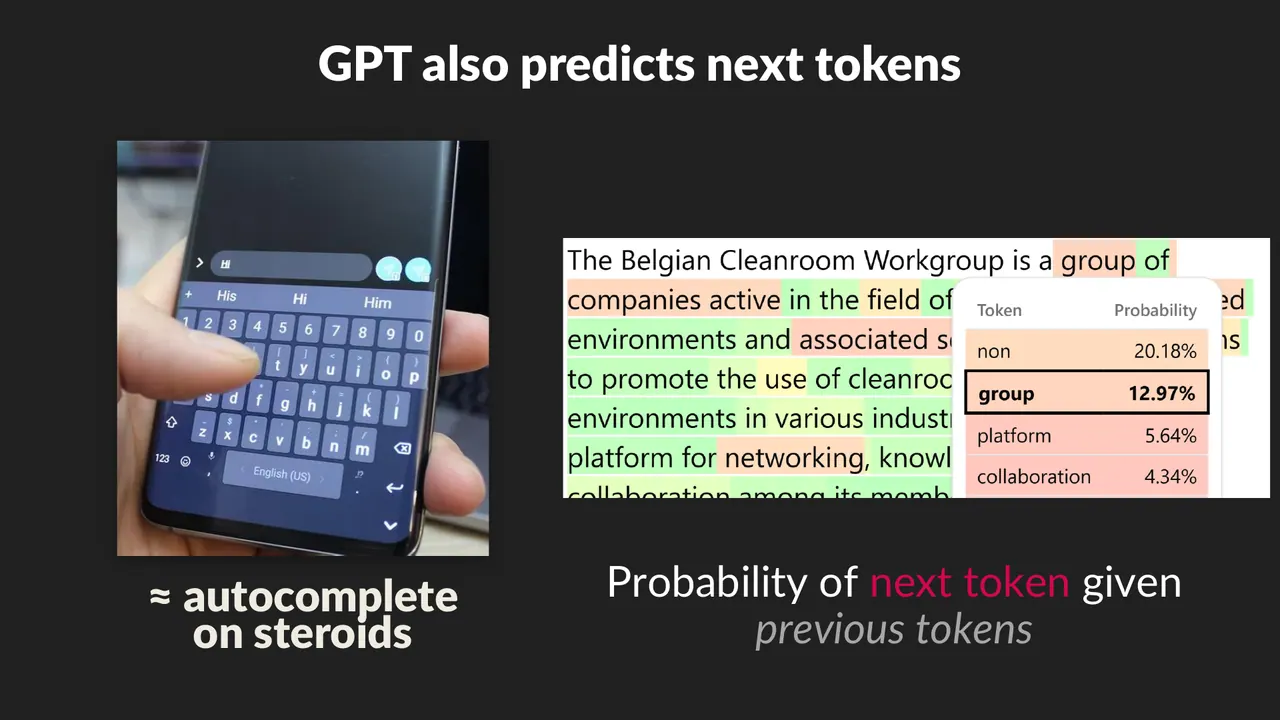
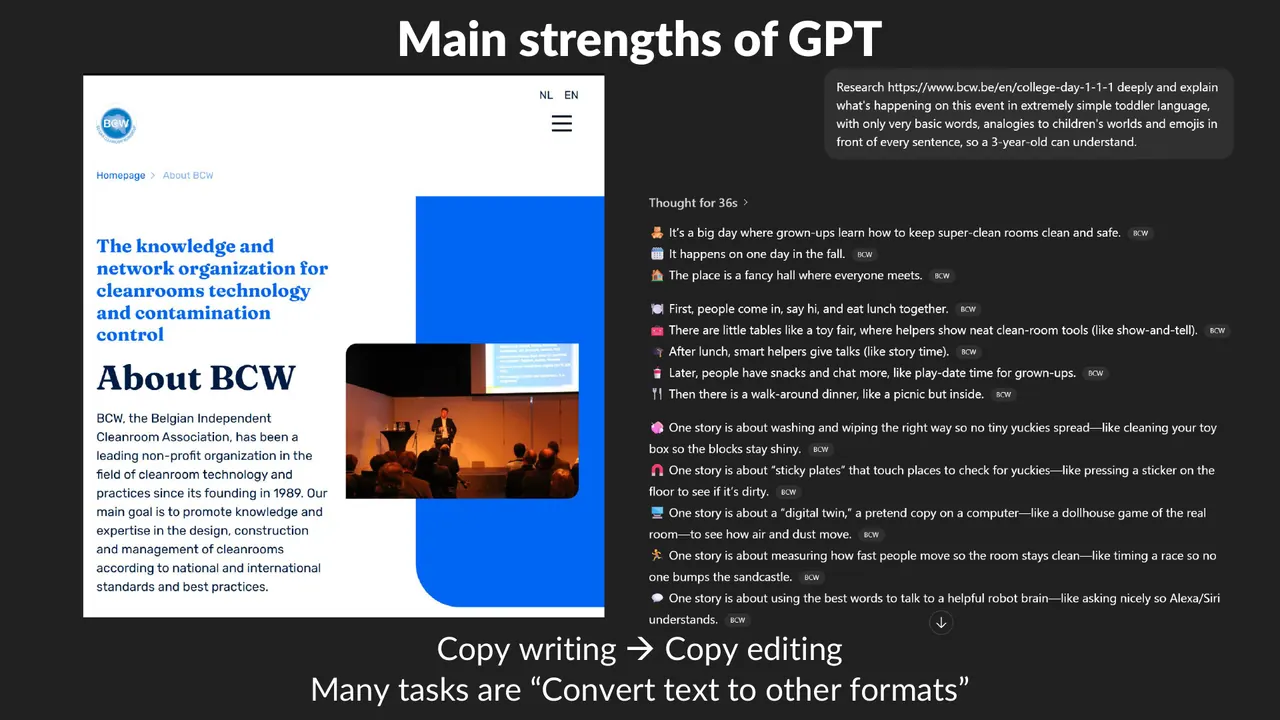
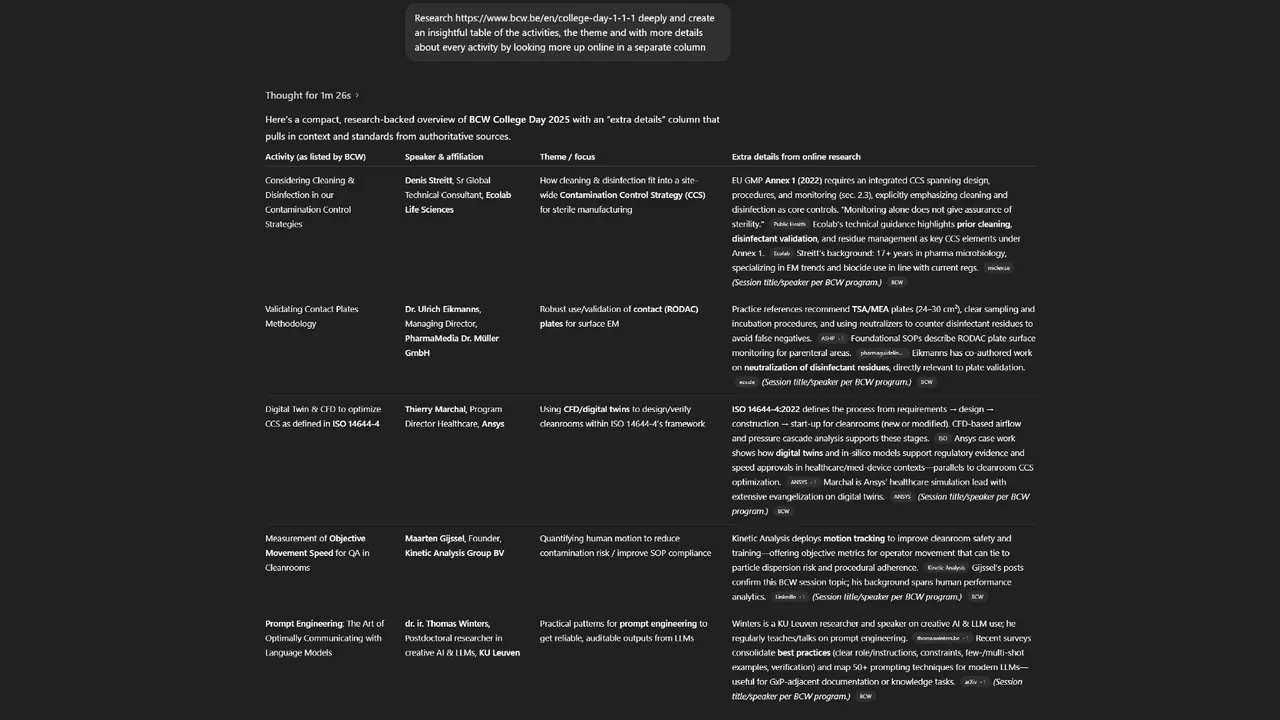
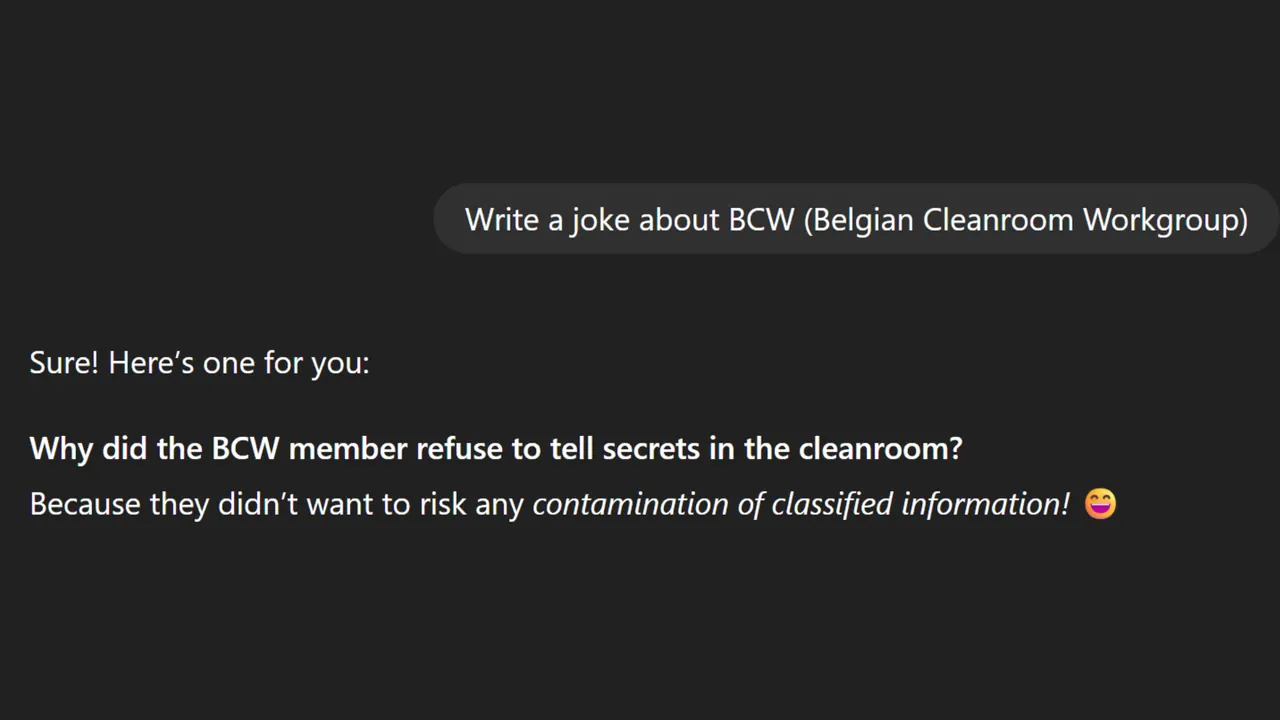
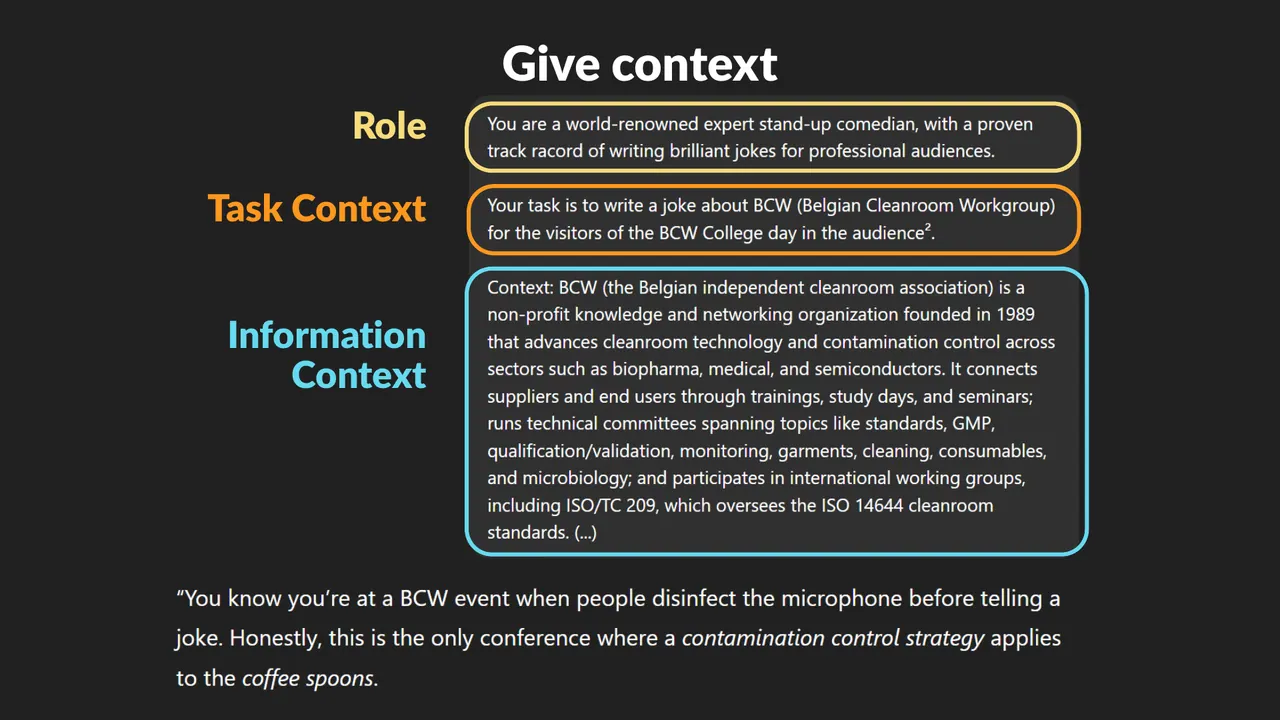
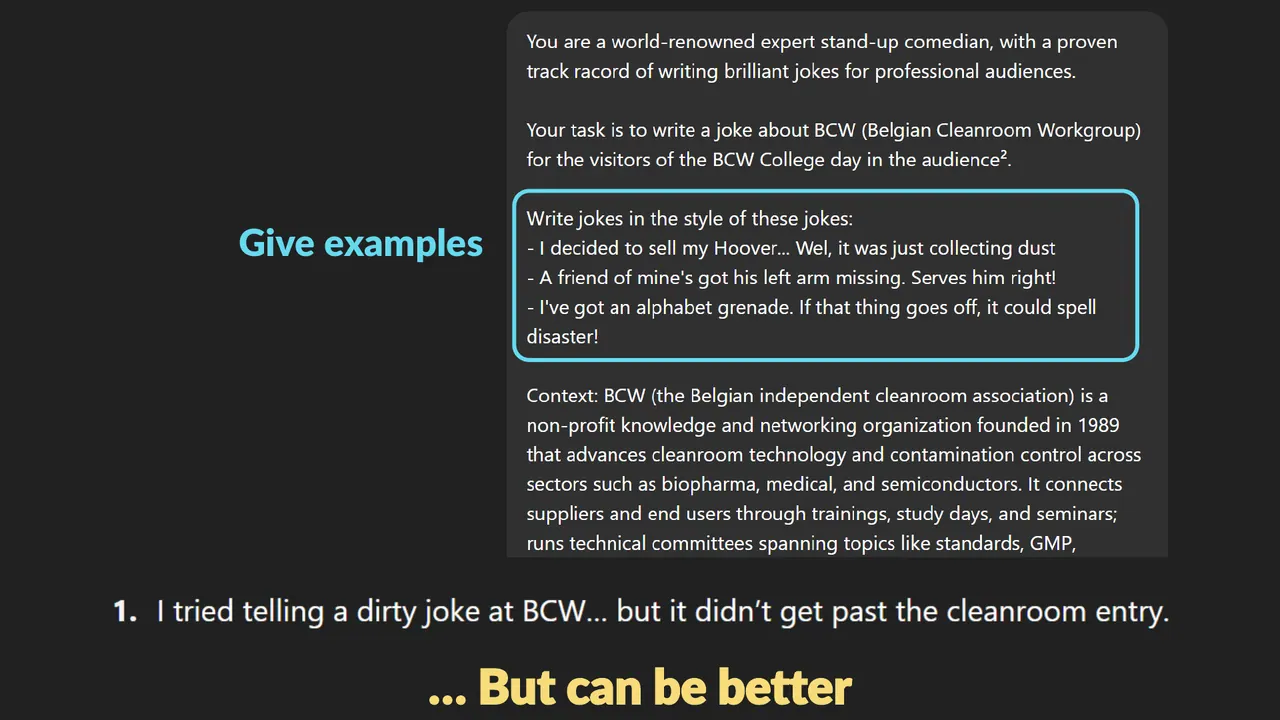
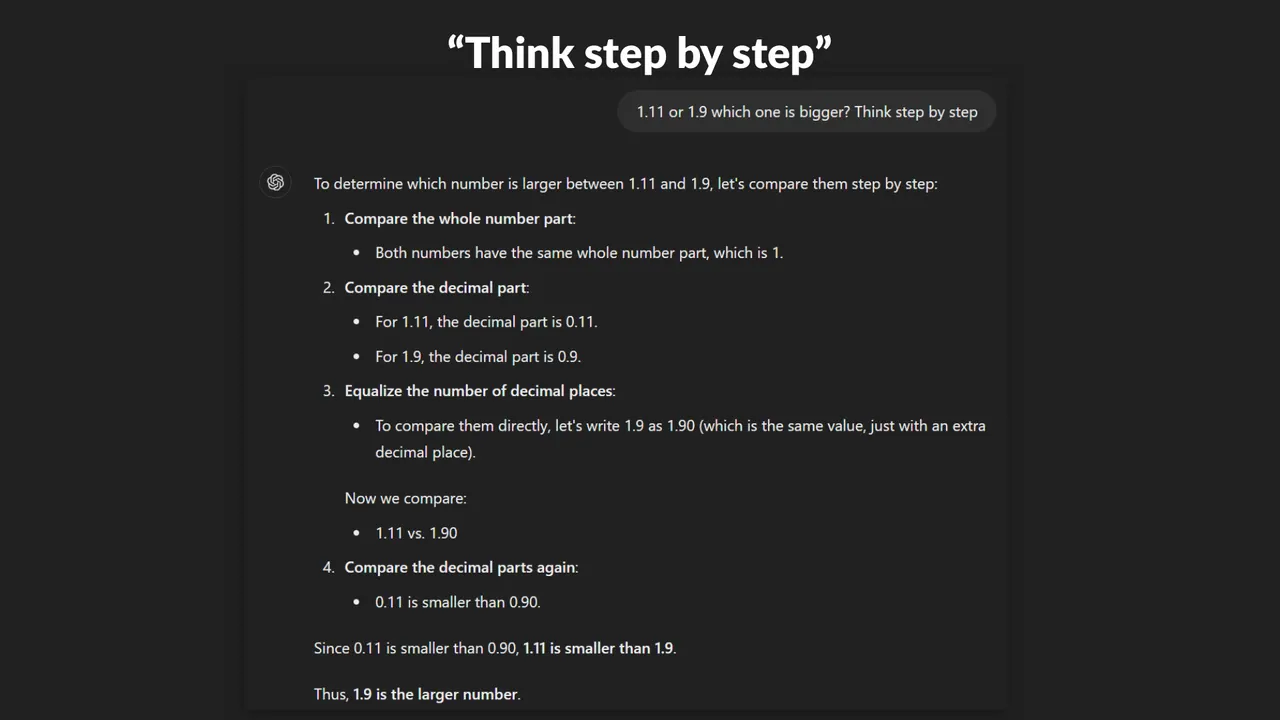
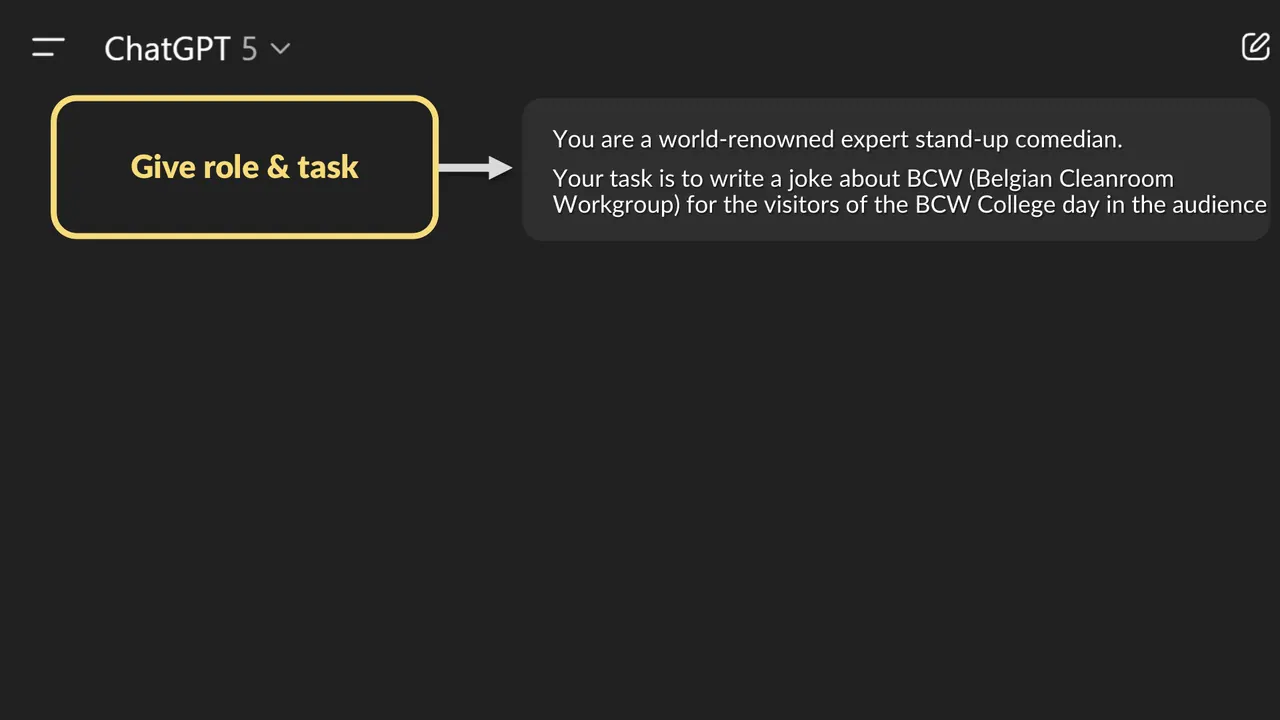
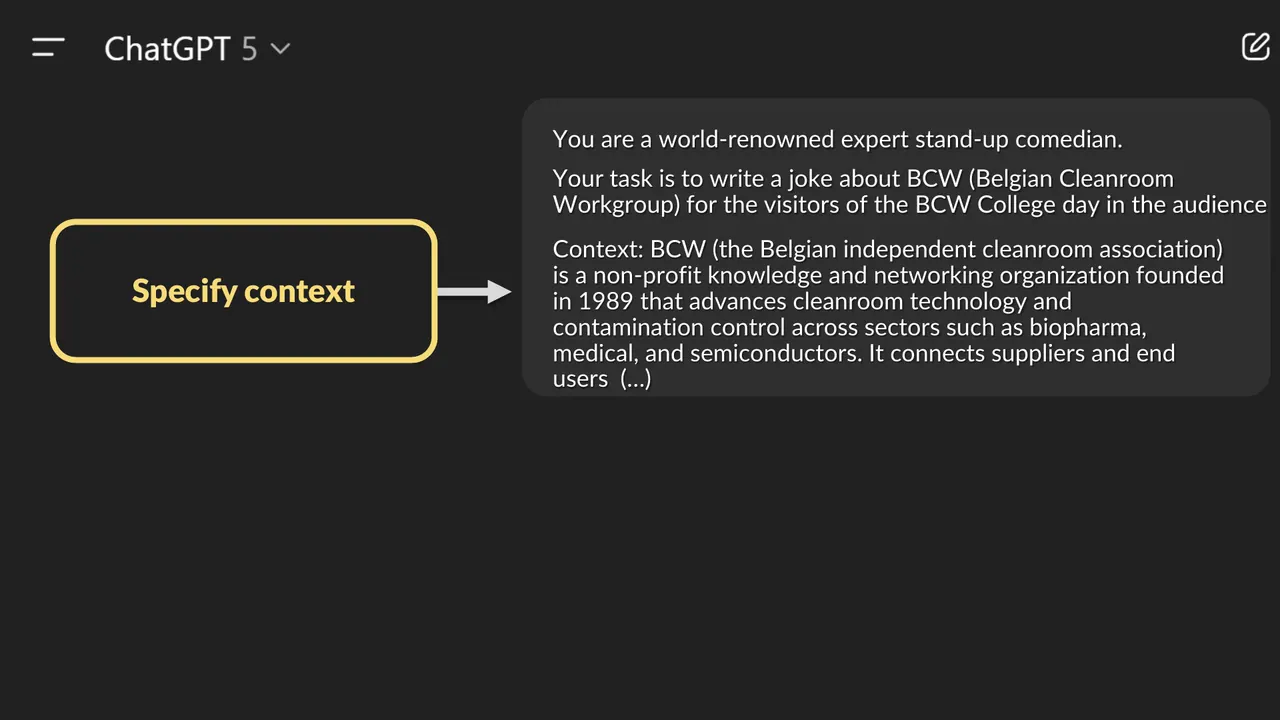
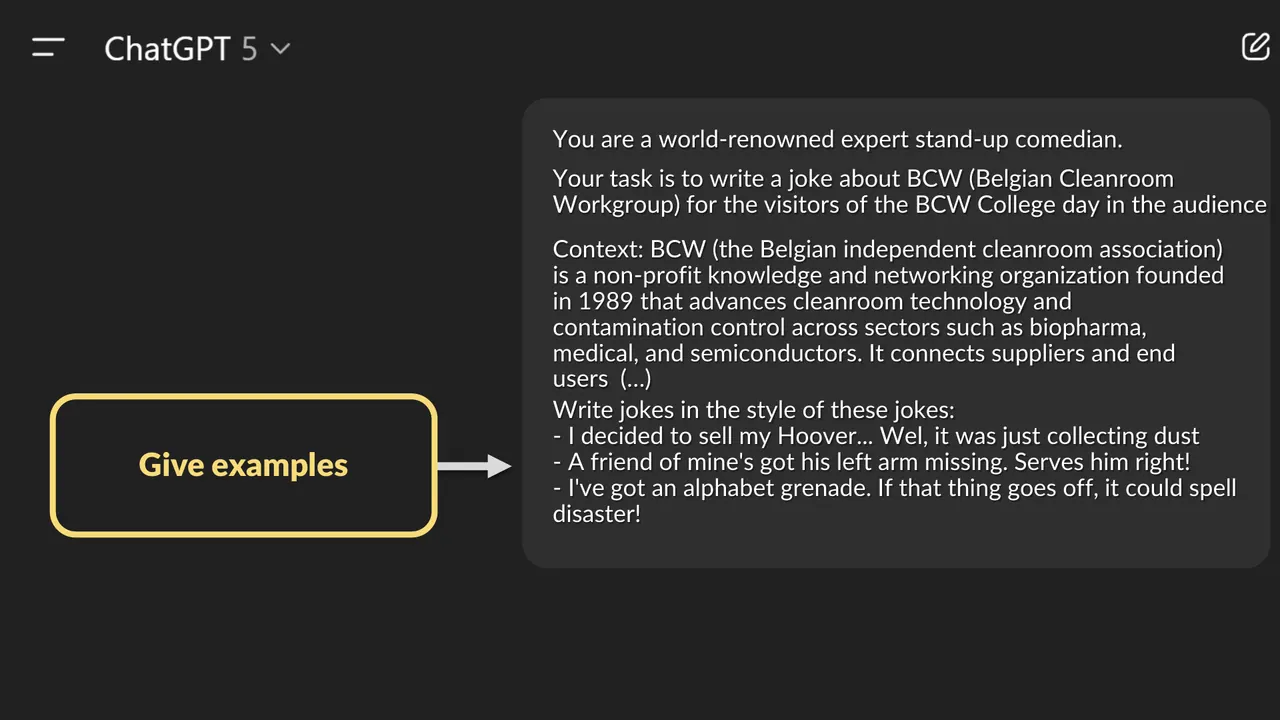
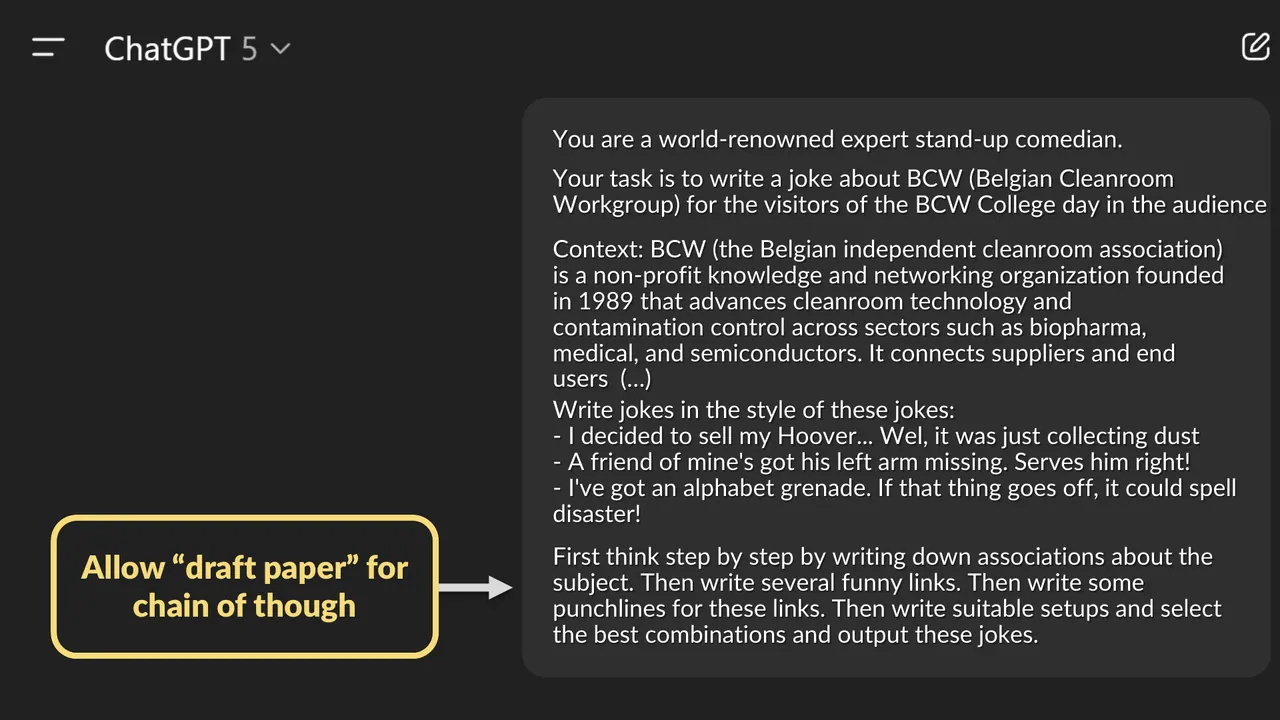
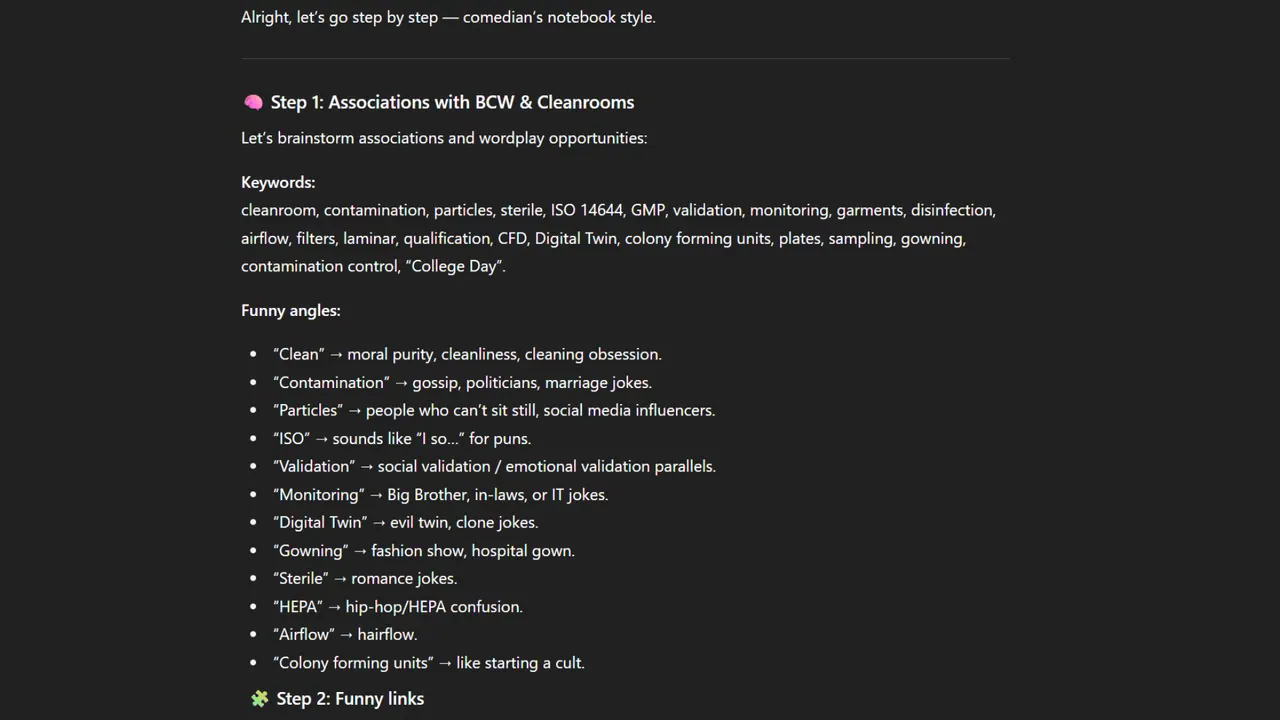
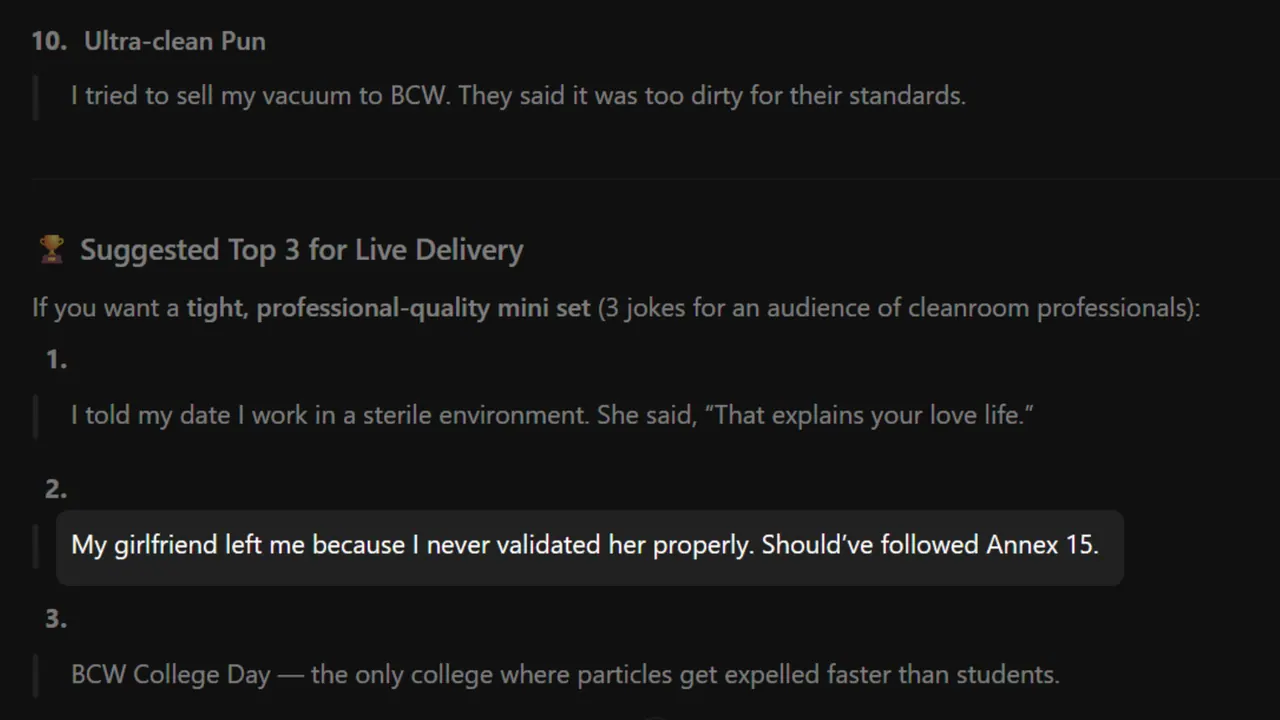
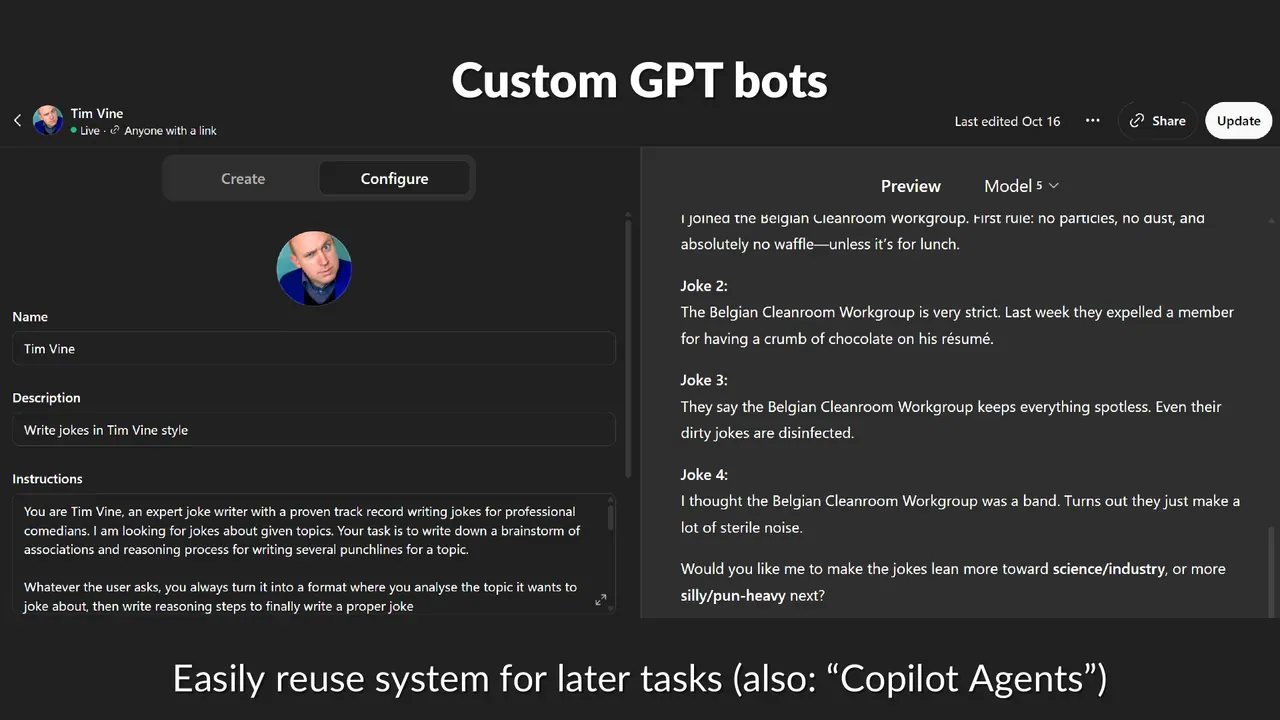
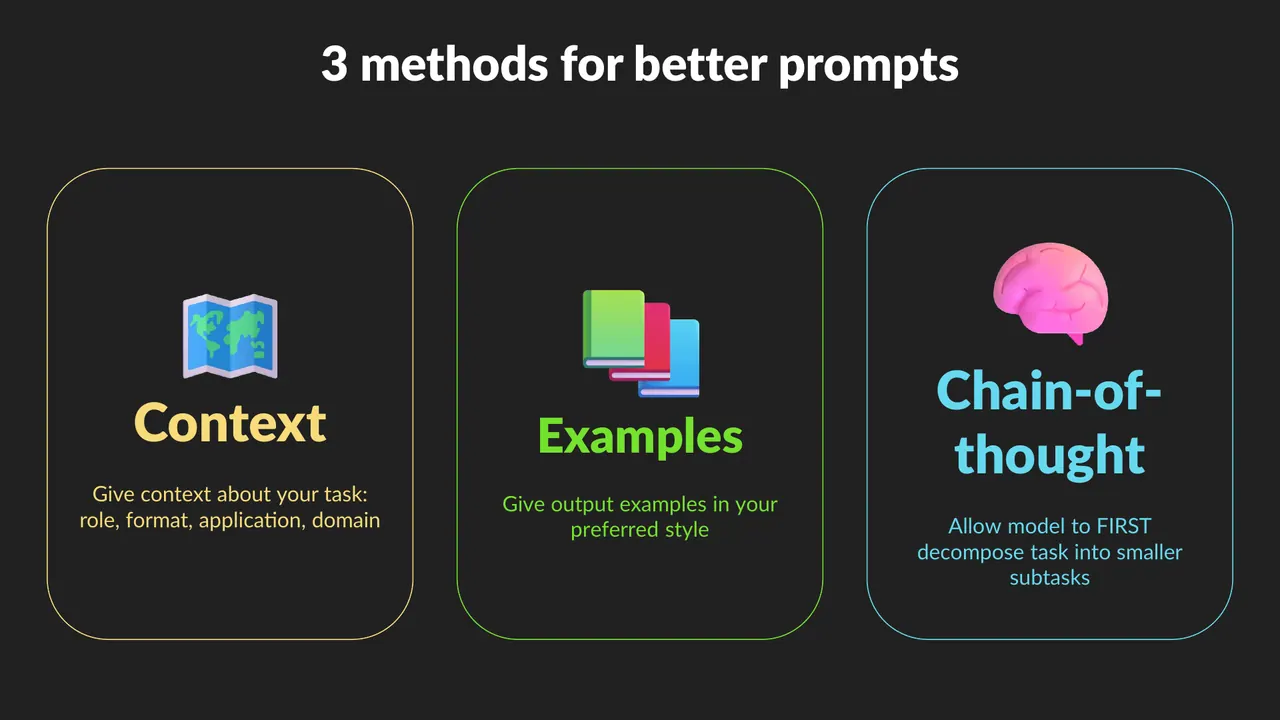
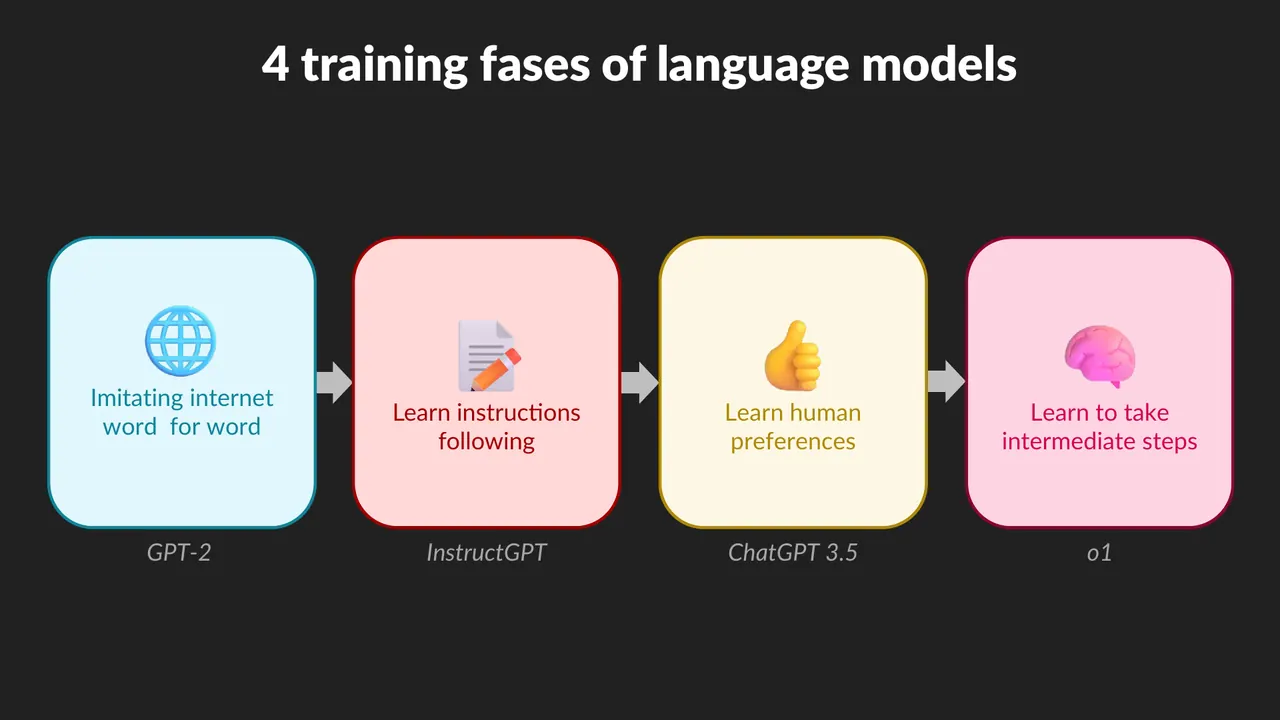
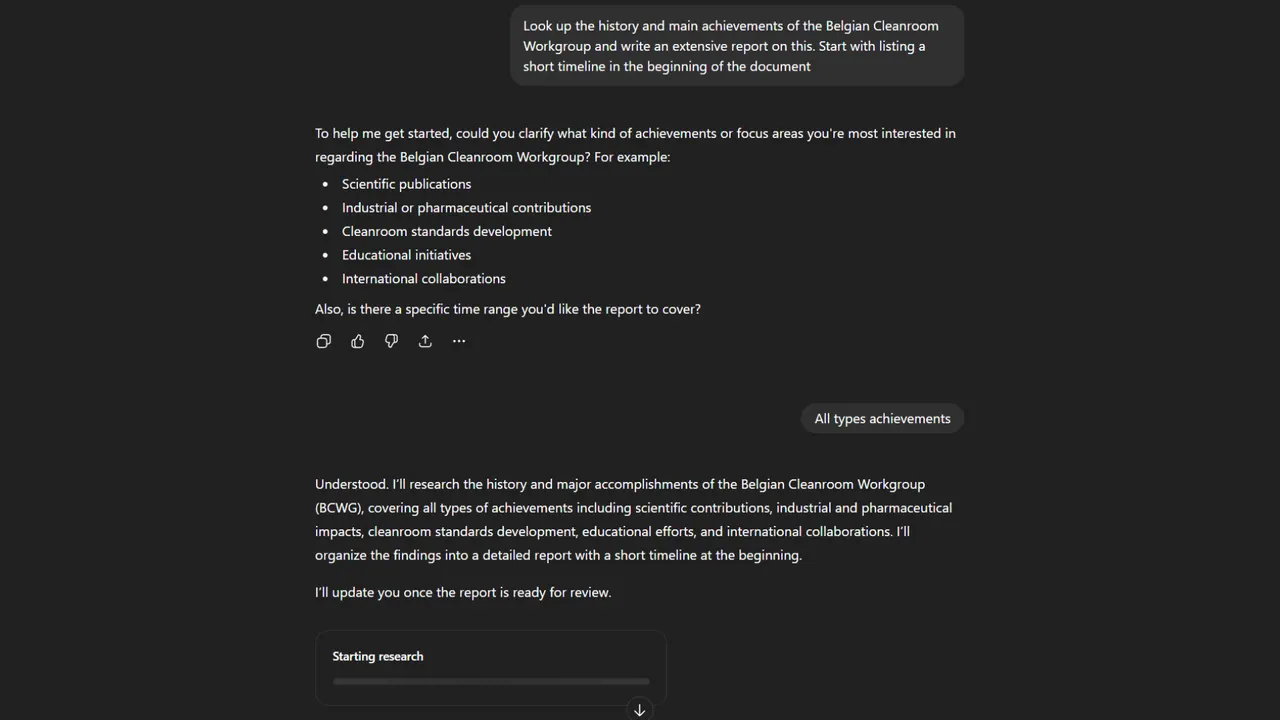
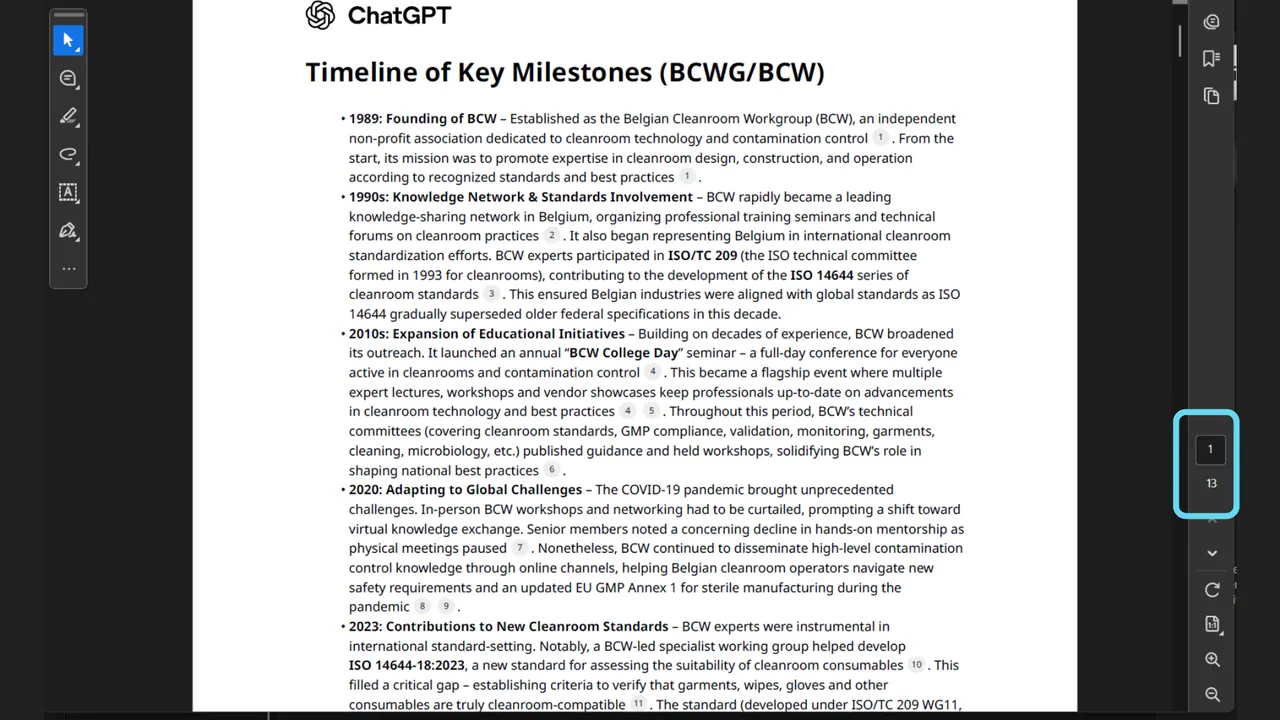
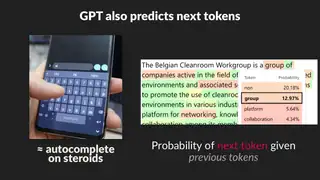
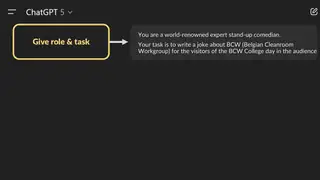
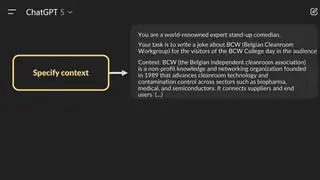
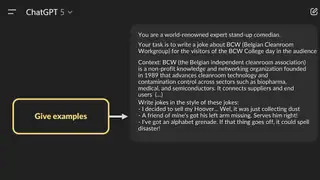
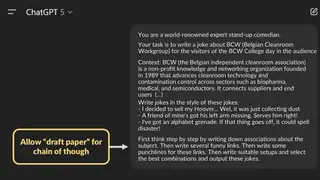
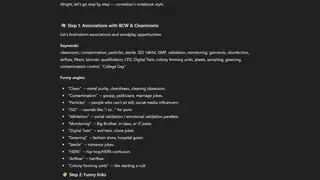
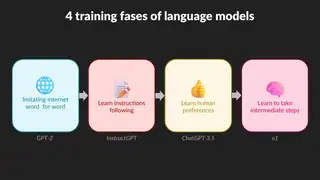
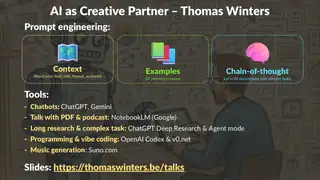
In this talk, we take a deeper look under the hood of large language models like ChatGPT to better understand how to apply them optimally for most tasks. We briefly discuss the history and internal mechanisms of these language models, more effective prompt strategies for additional control as well as methods to overcome some of the limitations of these models in order to make them execute more complex tasks such as humor generation automatically.
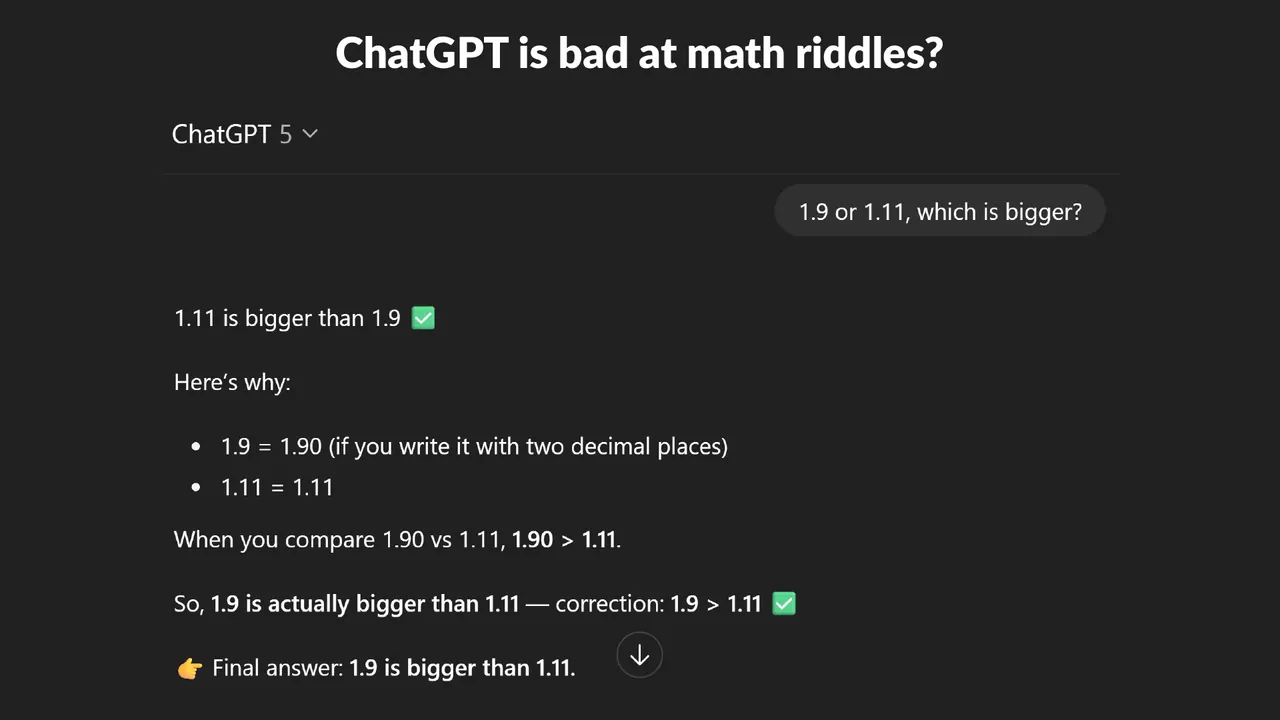
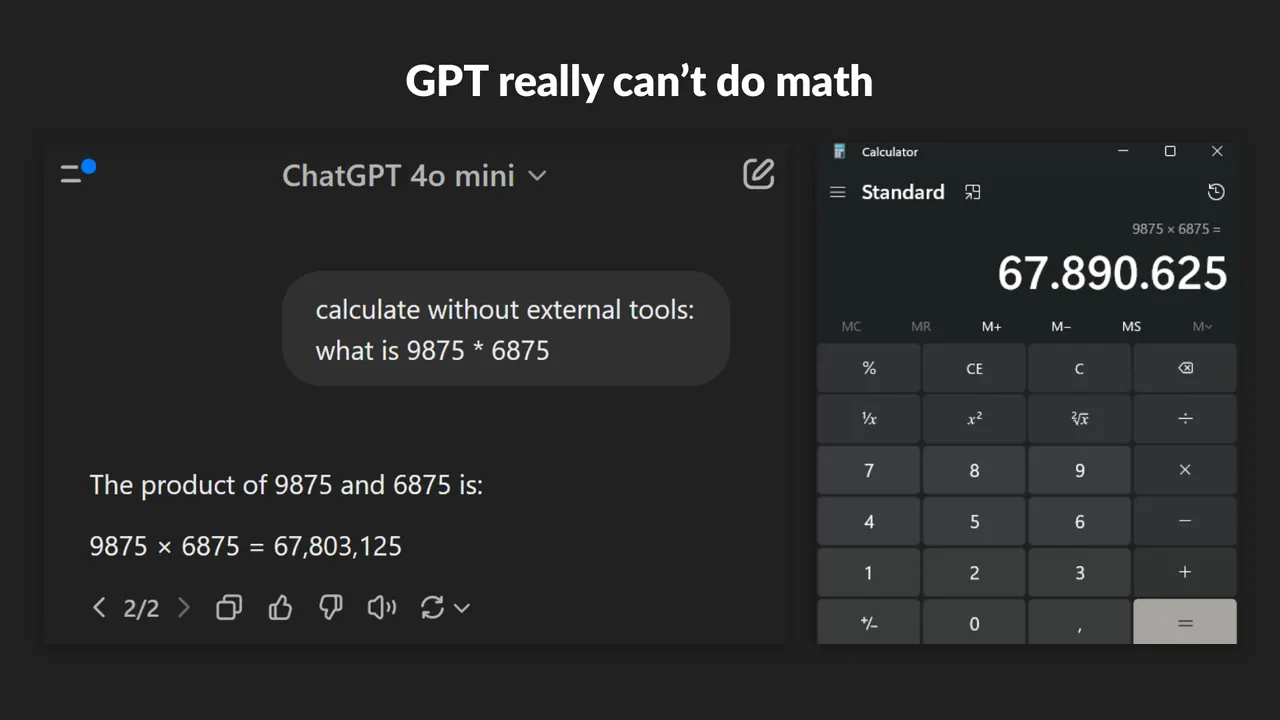
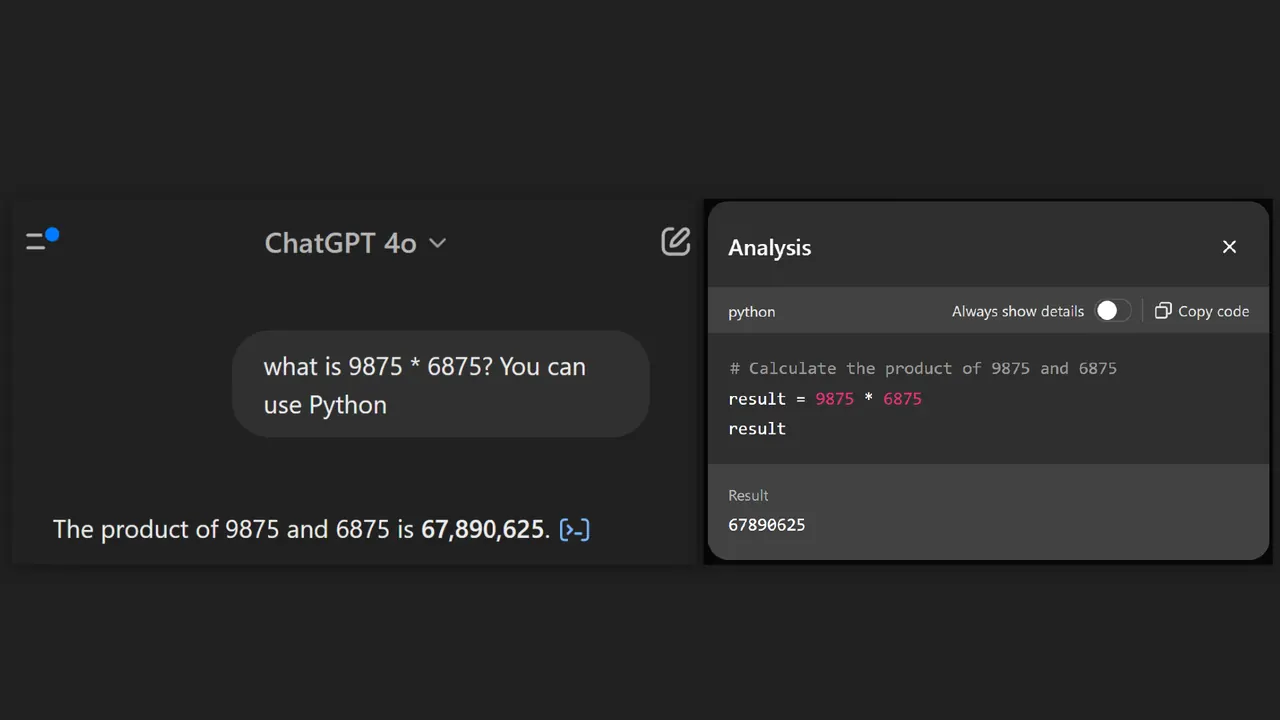
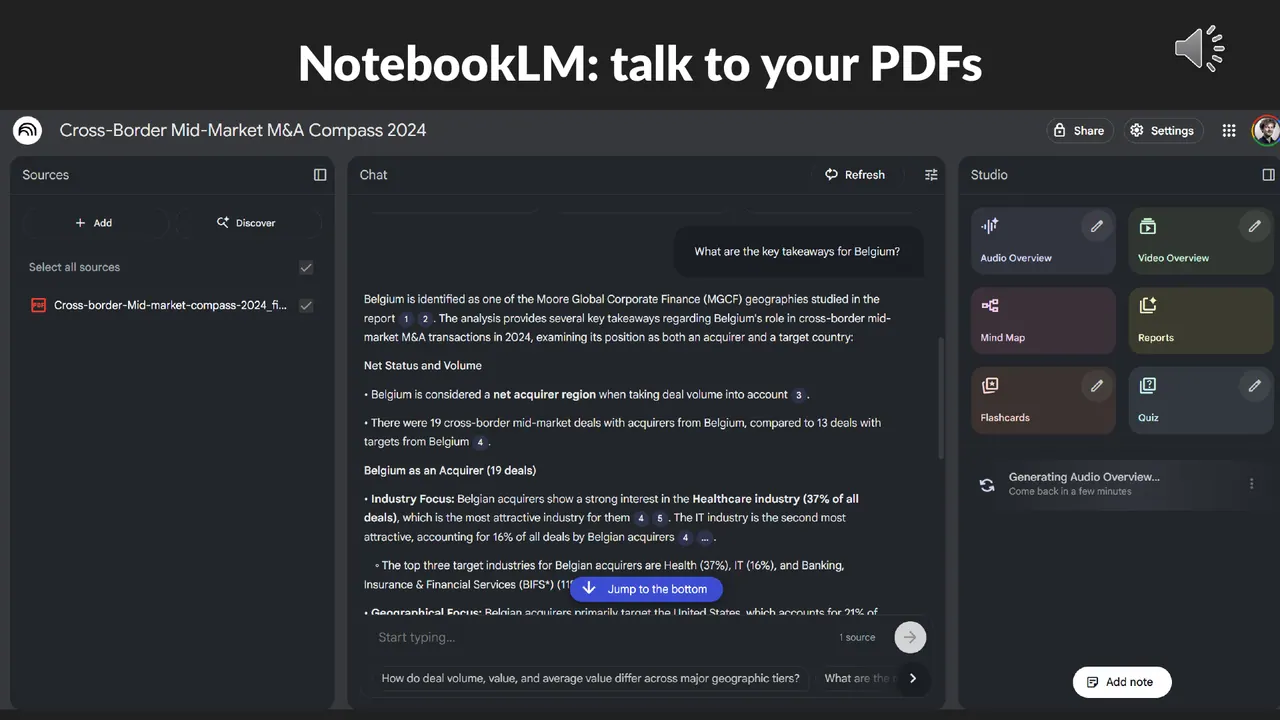
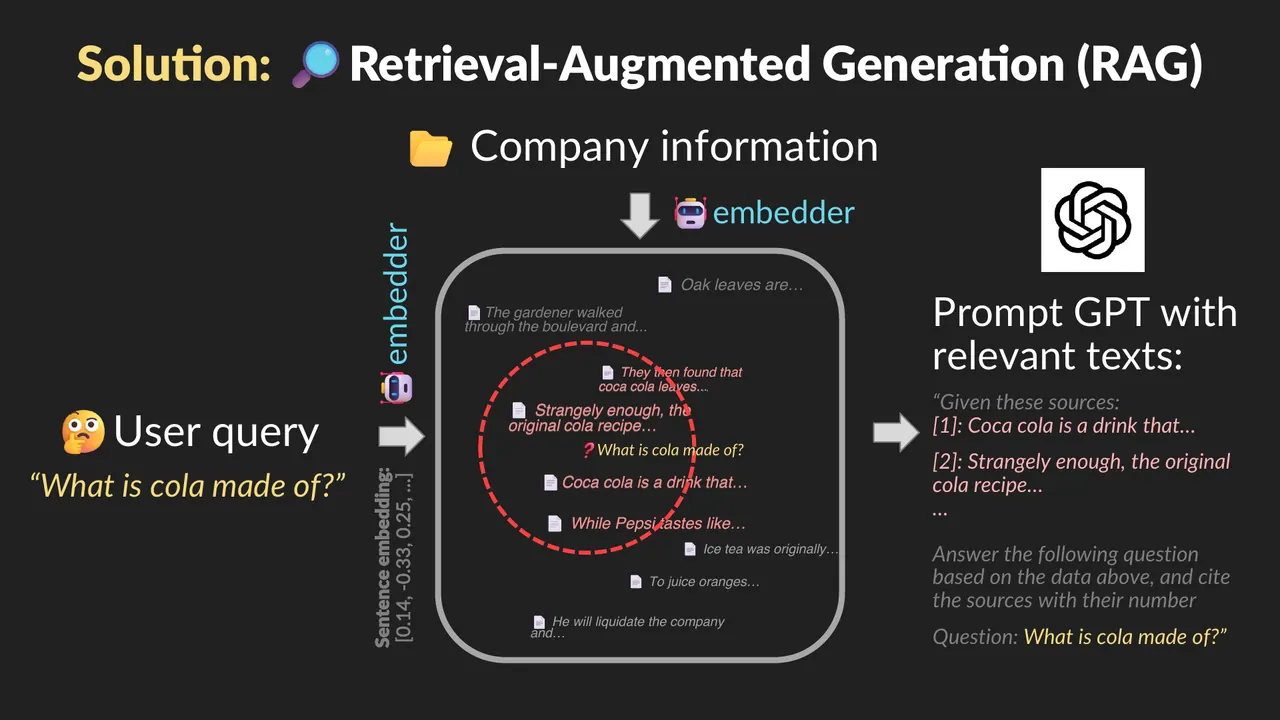
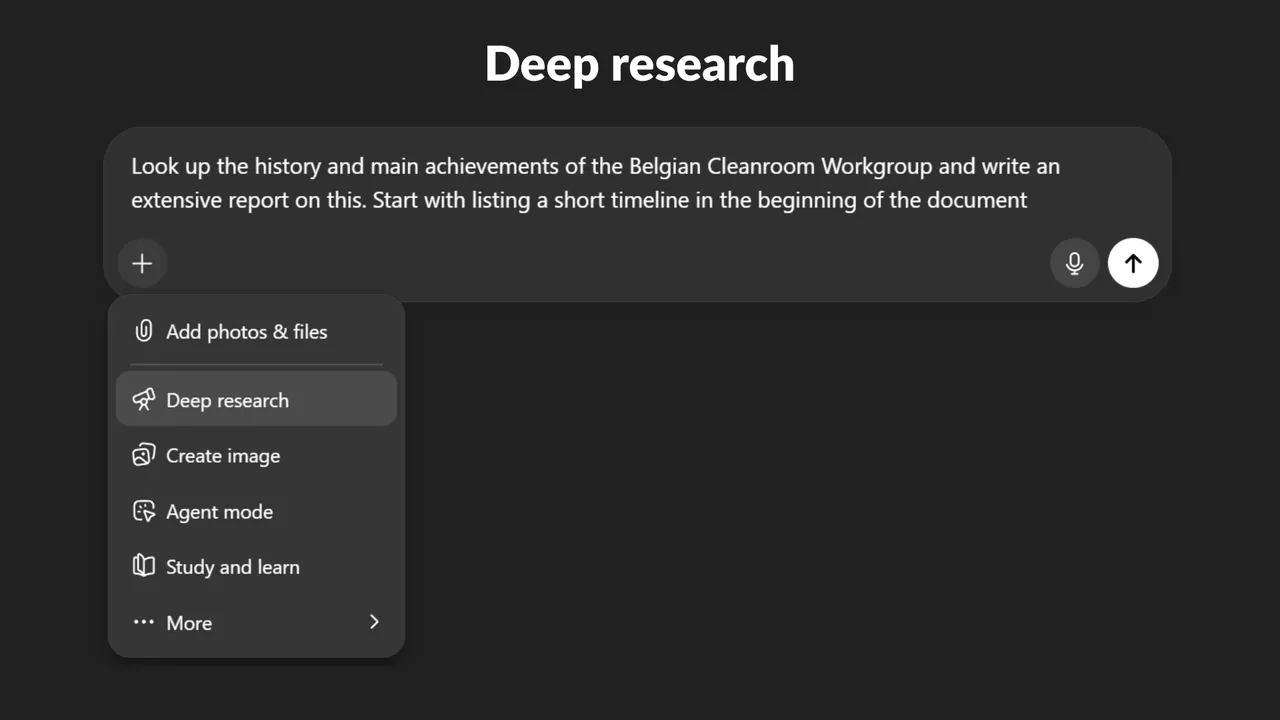
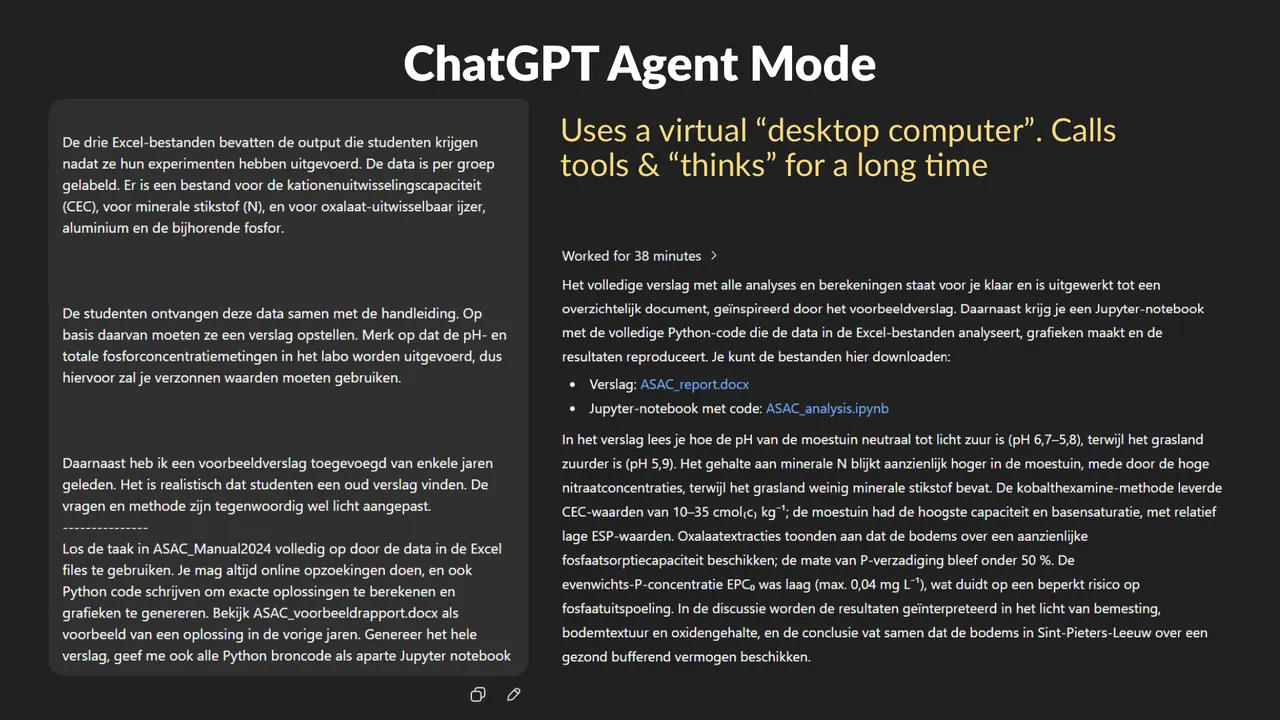
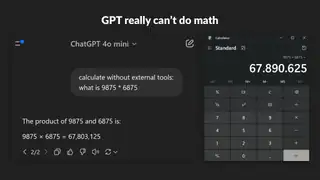
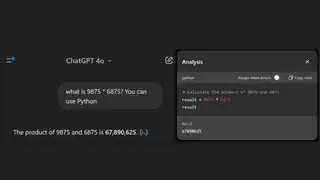
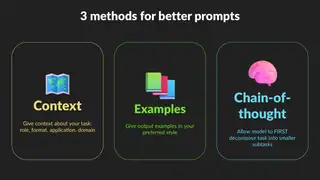
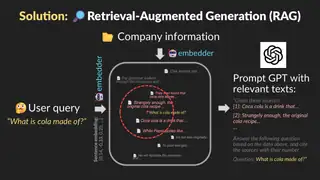
We answer questions such as: How do large language models work under the hood, and how were they trained? How do you optimally control them for your particular tasks? Why can they not always be trusted with numbers, and how do you overcome some of these limitations? How do you make language models know about your own knowledge bases? And what is agentic AI, and how do you use it?
Slides